Scaling Enterprise Agentic AI: Why the MSI EdgeXpert 64GB Model Changes the TCO Game
AIoT Solutions
As enterprises transition from simple conversational LLMs to autonomous, 24/7 Agentic AI, infrastructure needs are shifting dramatically. While central development requires maximum headroom, deploying hundreds of active agents across factories, regional offices, and retail sites demands an optimized unit cost.
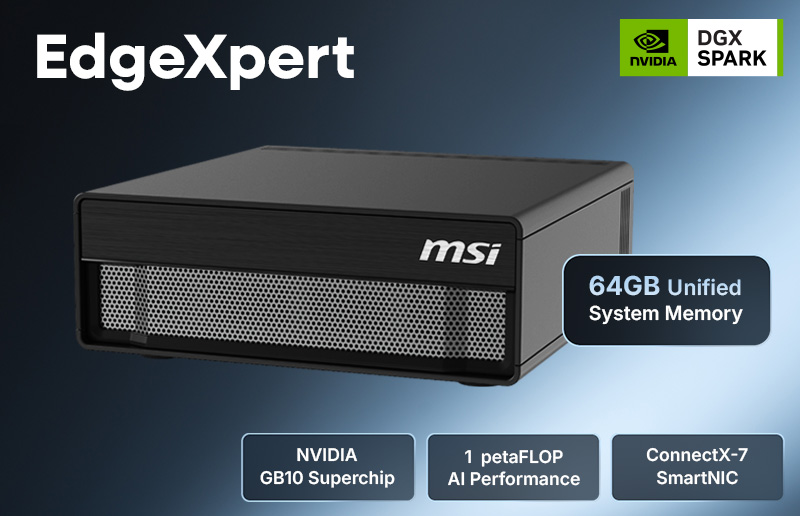
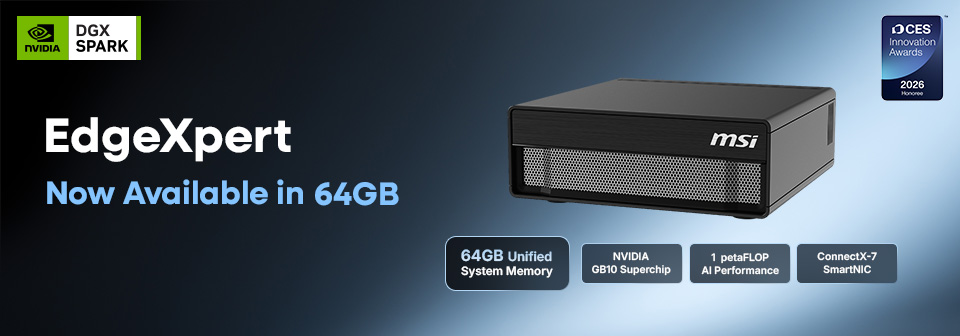
To bridge this gap, MSI is introducing the EdgeXpert 64GB configuration—built on the NVIDIA DGX Spark platform. By retaining the exact same NVIDIA GB10 Grace Blackwell Superchip while tailoring memory capacity, enterprises now have a lean, highly scalable path to deploy on-premises AI fleets.
1. Flexible Stacking: Matching Hardware to Model Scale
A core strength of the EdgeXpert architecture is its native multi-node expansion via high-speed networking. Whether you deploy a standalone desktop unit or stack multiple nodes, performance scales linearly. NVIDIA Sync can also be utilized to help teams set up a cluster of connected systems and monitor CPU and GPU activity from one desktop app.
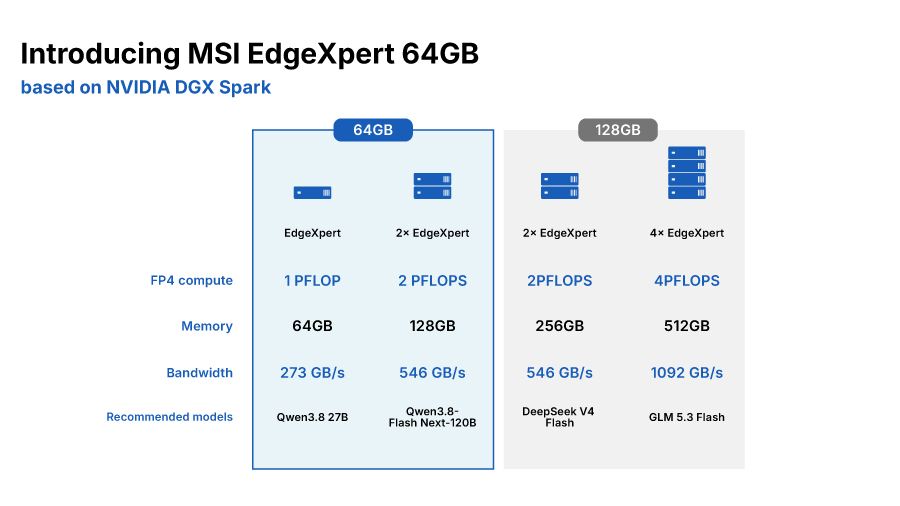
Whether running a compact single-node setup at a remote site or stacking nodes to handle massive Flash-architecture models, the platform delivers predictable, linear compute growth.
2. Identical Platform Architecture: "Develop Big, Deploy Lean"
A common challenge in AI deployment is software fragmentation—having to rewrite code when moving from developer rigs to production edge units. The EdgeXpert 64GB eliminates this friction entirely.
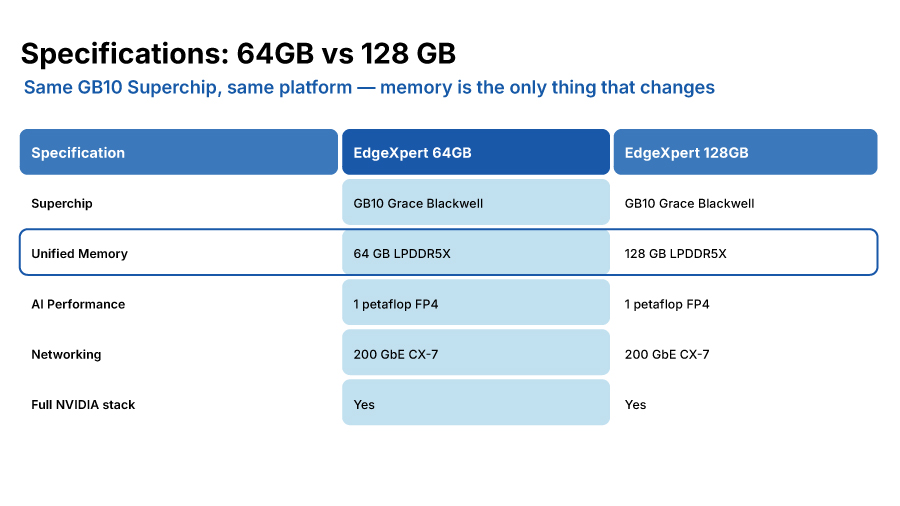
Same superchip, same platform—memory is the only thing that changes. Teams can perform prompt engineering and initial evaluation on 128GB units in the HQ AI Center, then push the exact same containerized agent software to 64GB edge units without touching a single line of code.
3. Real-World Usability: What Fits on the 64GB Model?
Memory capacity directly impacts the context length and KV cache available for multi-turn reasoning. Accounting for about 8 GB OS overhead, the EdgeXpert 64GB leaves approximately 56 GB of usable memory for model weights and KV cache.
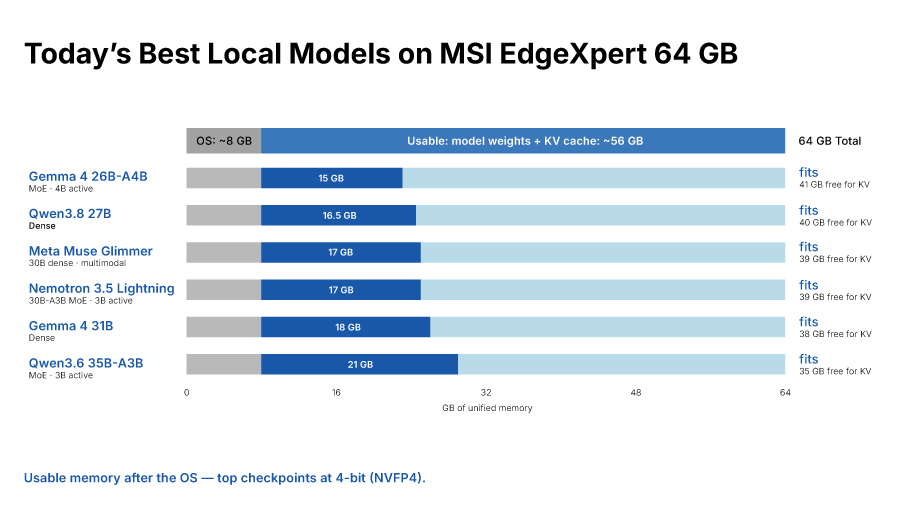
Even with dense 30B+ or MoE models loaded, the system reserves 35 GB to 41 GB of memory purely for KV cache, ensuring fast token generation and deep contextual memory during continuous agent execution.
Summary: A Purpose-Built Solution for Edge AI Fleets
By pairing the 1 PFLOP FP4 performance of NVIDIA GB10 Grace Blackwell Superchip with 64GB of high-speed LPDDR5x memory, the new MSI EdgeXpert SKU offers an unbeatable combination of power, thermal efficiency, and unit-cost economy.
Whether automating factory quality control, processing secure banking documents, or hosting local clinical voice agents, the EdgeXpert 64GB provides the exact footprint required to bring production AI directly to your operational data.